By Ronnie Mbuqe
A usable system combines data preparation, a model, application rules and monitoring. The model's output is one input to the decision rather than the whole service.
For a document assistant, retrieval supplies passages while access controls decide which passages a user may see. Accurate generation cannot compensate for exposing the wrong person's documents.
RM
Ronnie Mbuqe
Author · ExplainItSimply
24 July 2026
7 minute read
English
What Makes AI Work?
Where the building blocks appear
A chatbot, fraud alert and image classifier look different, but each depends on prepared data, a trained model, evaluation and ordinary software around the prediction.
What understanding them helps with
You can ask whether weak output came from the examples, the model, missing context, connected tools or the rules of the application instead of blaming one mysterious box.
An AI result may look like one instant answer, but several systems usually worked together to produce it. Data supplied examples, training adjusted the model, software prepared your request, computing infrastructure ran the model and safety or business rules shaped what could be returned. Understanding those pieces makes it easier to see both the power of AI and the places where errors can enter.
Behind the result
The pieces that make modern AI systems useful
Modern AI products combine more than a trained model. They need data pipelines, software that prepares inputs, a model that performs inference, instructions that shape behaviour, safety checks, application code and often ordinary databases or search systems. The polished answer a user sees is the final step in a larger software pipeline.
What Makes AI Work in a real situation
A support assistant for a company might first identify the customer, search approved help documents, place the most relevant text into the model context, generate a draft answer and then apply rules before showing it. The language model is important, but it did not magically contain the company’s current account data or private policy documents unless the application deliberately supplied that information.
What makes this useful
Thinking in building blocks makes AI easier to evaluate. When an answer is wrong, the cause may be poor source data, a bad retrieval result, an ambiguous instruction or the model itself. Treating every problem as “the AI was wrong” hides the part of the system that actually needs improvement.
A common point of confusion
Training is not the same as searching the web live. A model can use patterns learned during training, while an application can separately connect it to current databases, APIs or search tools.
Why do labels change what an AI system learns to predict?
A supervised model compares predictions with a target supplied in its training examples.
Trace the explanation
If that target measures clicks, the model is not automatically learning long-term usefulness. Choosing the target is a human design decision with practical consequences.
Source and further reading: Google developer documentation
Why the boring software around AI matters
A language model can generate an impressive answer and still be only one service inside a product. The application needs authentication so the right user sees the right information, permissions so the model cannot access data it should not see, logging so failures can be investigated, rate limits so one user cannot consume unlimited resources, and ordinary deterministic code for rules that must always behave the same way. These surrounding pieces are often less visible than the model, but they are what turn a demonstration into a service people can trust.
The same is true for evaluation. A team needs examples of good and bad outputs, measurable criteria and a process for testing changes. If a new prompt makes one scenario better but another worse, the team needs evidence instead of relying on a few impressive screenshots. Mature AI work therefore looks surprisingly similar to mature software engineering: version changes, test them, monitor them and keep a human responsible for the release.
Frequently Asked Questions
Questions about this article
What are the basic building blocks of an AI system?
Data to learn from, a model that finds patterns in that data, and rules for how the output gets used once it is produced.
Why does the quality of training data matter so much?
A model can only learn patterns that exist in its data, so gaps, errors or bias in the data show up later as gaps, errors or bias in the results.
Can a good interface fix a weak underlying model?
No. A polished screen can hide a weak result temporarily, but it cannot make an unreliable prediction accurate.
What is a model?
A model is the mathematical system trained to transform inputs into useful predictions or generated outputs based on patterns learned from data.
What is inference?
Inference is the stage when a trained model is actually used on a new input, such as generating an answer to a prompt.
Why add retrieval to an AI system?
Retrieval can supply current or private source material at request time so the model can answer from information that was not necessarily part of its training.
Where do normal software rules still matter?
Everywhere around the model: authentication, permissions, billing, data validation, logging and deterministic business rules remain ordinary software responsibilities.
Practical points to remember
Key takeaways
- Data gives the system examples to learn from.
- Algorithms provide the steps for finding patterns.
- Models store what the system has learned.
- Prompts tell the model what the user wants.
- People still guide, test and correct important results.
Why can the same model behave differently in two apps?
Prompts, retrieved context, tools and output checks all affect the result. Different surrounding systems can therefore produce very different user experiences.
Compare the information and permissions supplied to each app before blaming or praising the model alone. The product includes the boundaries built around it.
The parts behind an AI answer
An AI product is more than a model. Data is collected and prepared, a model learns statistical patterns, software turns that model into a usable service, rules limit what the service may do, and people test the output. When any one of those parts is weak, the final answer can be weak even if the underlying model is powerful.
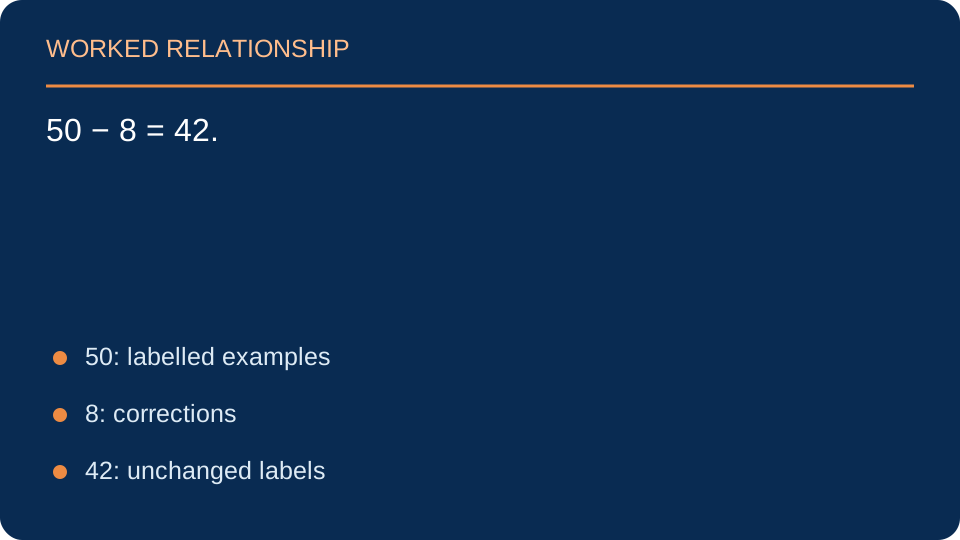
A toy training file has 50 examples and 8 labels need correction. How many labels are left unchanged?
Trace the explanation
50 − 8 = 42. Incorrect labels can teach the wrong relationship; correcting them is different from merely adding more examples.
Source and further reading: Google developer documentation
A model without a retrieval system cannot automatically inspect your latest booking
A trained model may know general patterns while having no access to a particular database record. To answer about a live booking, an application needs an authorised way to fetch relevant data and provide it to the model or use a controlled tool. General language ability and current account access are separate capabilities.
Follow a request for a cancellation rule. First authenticate the caller and retrieve the allowed booking; then obtain the applicable policy; finally present the result with its conditions. The model should not invent a missing policy or gain access to other customers simply because the conversation sounds natural.
Authorised data retrieval to Checked answer to the user
Which part should decide whether a user may view booking 42?
The application's trusted authorisation layer. A model's friendly response or guess about identity is not a permission check.
Follow One AI Answer From Start To Finish
Consider asking an AI system to classify a photo as a cat or a dog. Before the model can answer, the image is converted into numbers. During training, examples with known labels are used to adjust the model so its predictions become less wrong. After training, a new image travels through the learned network and the model produces scores representing how strongly the input matches patterns associated with each class.
The same basic training idea scales to language models, although the data and model are far larger. Text is broken into tokens, relationships between tokens are learned across huge collections of examples, and the model is repeatedly adjusted to improve predictions. Later tuning and human feedback can shape the behaviour toward more useful answers.
What matters is that the final answer is the end of a pipeline. Data quality, model design, training objectives, evaluation and the application around the model all influence what the user eventually sees. If one layer is weak, a polished interface cannot magically make the result reliable.
A team wants helpful recommendations but trains only on clicks. What mismatch could arise?
One reasoned response
An attention-grabbing item can win a click without helping the reader. Define usefulness and evaluate it with evidence beyond the easiest available measurement.
Source and further reading: Google developer documentation
How the building blocks fit together
An AI application is not just a model. It is a complete system that receives information, prepares it, uses a model, presents a result, and gives people a way to respond. A useful way to understand the parts is to trace a simple support-message sorter.
- Input: a customer writes a message. The application checks that it is not empty and removes or protects information that does not need to be processed.
- Representation: the message is converted into a form the model can work with, such as tokens or numerical features. This step affects what distinctions the model can notice.
- Model: learned parameters are used to estimate a category or produce an output. The model does not automatically know the company's current policy unless the system supplies reliable context.
- Decision rule: a threshold or business rule determines whether to route the message automatically, ask for clarification, or send it to a person.
- Feedback and monitoring: staff can correct misrouted messages. The team analyses patterns in those corrections before deciding whether to adjust the model.
Why the surrounding system matters
A strong model can still be part of a poor application if the input is incomplete, the instructions are ambiguous, or the output is displayed without context. A sensible design shows uncertainty when it matters, logs only what is needed, prevents unauthorised access, and provides a manual route when automated processing fails.
Example of a failure chain
Suppose a customer writes, “I cannot get into my account after changing my phone.” If the system focuses on the word “phone,” it might classify the request as a device problem rather than account access. A staff member can correct it, but if the system never records or reviews that type of error, the same problem may continue. The fix might involve better examples, clearer categories, or a rule for messages that mention both a device and an account.
Try this: for any AI feature you use, identify its input, the output it creates, who checks the result, and what happens when it is wrong. This simple map often reveals more about reliability than the label “AI-powered.”
Further reading: Google's Machine Learning Crash Course; NIST AI Risk Management Framework.
Follow one example through the building blocks
Imagine a library wants to help visitors find books by topic. The project begins with a goal: recommend useful books, not merely popular ones. The team needs examples of book descriptions, subject labels and feedback, and it must decide what counts as a good recommendation. Those choices shape the system before a model is selected.
Data, representation and objective
Descriptions may contain useful words, but they can also omit context or reflect old cataloguing practices. Labels are human decisions, not perfect truths. A model learns patterns from the representation it receives and is optimised for a chosen objective. If the objective rewards clicks alone, it may recommend attention-grabbing books rather than the most helpful ones.
Evaluation and human feedback
The team should test recommendations on examples that were not used for training and ask a varied group of readers whether the results are relevant. It should look at both average performance and cases where the system repeatedly misses a reader's need. Staff need a way to correct categories and explain how recommendations are generated at a useful level.
Why the whole system matters
A model is only one component. Data collection, labels, the goal, interface design, privacy, monitoring and the ability to appeal all influence the final experience. When an AI product fails, ask which part of this chain failed instead of treating “the algorithm” as a complete explanation. This systems view transfers to search, fraud detection, translation and many other applications.
Sources
Sources and further reading
A closer lookA label quietly defines the task
A training dataset marks a message as urgent whenever it contains the word today. A model can learn that shortcut while missing urgent messages without that word.
Work through the distinction
Inspect how labels were created and examine errors, not just the final score. Data quality includes whether examples represent the intended concept. More examples of the same misleading rule may reinforce the problem.
What needs investigating?
Choose an answer to see feedback. You can try again.
Show the answer and explanation
The label definition and error cases. Inspect how labels were created and examine errors, not just the final score. Data quality includes whether examples represent the intended concept. More examples of the same misleading rule may reinforce the problem.