By Ronnie Mbuqe
We observe its outputs: text, images or actions under particular conditions. Humanlike wording alone does not establish humanlike understanding or subjective experience.
Compare behaviour on controlled tasks, including unfamiliar cases and requests it should decline. That produces more useful evidence than treating a warm conversation as a window into a mind.
Use this guide to test claims about an AI system: separate an observed capability from a story about awareness, correctness or future consequences. It is a claim-checking route rather than another tour of AI products.
The short version
Test claims about learning against the real AI mechanism, and compare broad promises with today's measured capabilities.
Where the myth appears
A chatbot writes fluently, so it can feel conscious or certain. A narrow medical test performs well, so a headline claims it can replace an entire doctor.
What clear AI knowledge helps with
Understanding the tested task, data and error rate helps you separate a useful capability from a dramatic story that the evidence never proved.
Movies, headlines, and social media often exaggerate AI capabilities. Let's separate science fiction from reality and understand what AI can and cannot do.
Does sounding certain tell you how reliable an AI answer is?
A convincing tone can be generated without adequate evidence.
Trace the explanation
Reliability depends on the claim, task, evidence and evaluation. Ask what would establish the answer rather than using confidence or length as a substitute.
Source and further reading: NIST
The Best Way To Judge AI Is To Separate Behaviour From Assumptions
AI creates unusual myths because the output can look more human than the process actually is. When a chatbot says “I understand”, people naturally imagine the same kind of understanding a person has. In reality, fluent language can be generated by statistical models without personal memories, feelings or a human life behind the words.
The opposite myth is also common: “AI only predicts the next word, so it cannot do anything meaningful.” Prediction is central to language models, but a large trained model can use those learned patterns In short, translate, classify, write code and solve some multi-step problems. Saying how the mechanism begins does not fully describe the capabilities that emerge from it.
Another myth is that AI output is objective because it comes from a computer. Models learn from data created by people and are shaped by design choices, training methods and feedback. Biases, gaps and errors can therefore appear in the output. High-stakes uses need testing with real populations and a way to challenge wrong decisions.
The safest habit is to ask evidence-based questions. What task was tested? Against what benchmark? How often was the model wrong? Does it have access to current information? Who is responsible when the output causes harm? Those questions turn vague excitement or fear into something measurable.
Fluency is not certainty
A confident writing style does not prove the answer is correct. An AI tool can state a wrong historical date or an invented statistic in the same smooth, assured tone it uses for a fact it got right, which is why claims worth relying on are still worth checking against a source.
AI does not automatically know private facts
A model only knows information it was trained on, information supplied in the current system, or information retrieved through connected tools.
Human oversight is not magic either
People can also make mistakes. Good systems combine suitable automation with checks, accountability and evidence.
A confident answer and a correct answer are separate observations
A language model can produce fluent wording for a true statement or a false one. The grammar and certainty of the voice do not provide an independent fact check. Asking it to sound more certain changes the presentation, not the underlying evidence.
Try a claim containing a name, date and quotation. Check each item against the original source rather than searching for another page repeating the same claim. A fabricated citation can look complete, so open the source and confirm that it supports the statement.
Identify a specific claim to Judge the claim in context
A worked example and a common mix-up
A practical example
Consider a hiring-screening tool. It may rank applications using patterns learned from historical data. If past hiring favoured one type of candidate, the model can learn that pattern even if nobody explicitly wrote a discriminatory rule. The right response is not to assume AI is neutral or to assume it can never help. The organisation needs to test the criteria, monitor outcomes and keep humans accountable for the final process.
A common misunderstanding
The phrase “AI is taking over” hides many different questions. Automation can remove some tasks, create new tasks and change how existing jobs are performed. The effect depends on the industry, economics, regulation and how quickly organisations adopt the technology. A dramatic headline is not a workforce forecast.
A model gives two confident but contradictory answers. Which test is more useful than asking it to choose a firmer tone?
Trace the explanation
Treat the outputs as competing claims. Check definitions, assumptions and supporting evidence. A change in tone cannot settle which claim is true; the relevant source and conditions can.
Source and further reading: NIST
Why does a larger model not automatically win every task?
Useful performance depends on training, tools, task design and constraints as well as size. Cost, latency and reliability also matter in a real service.
A narrow document classifier can be a better fit than a general chatbot. Define the job first, then measure competing systems on that job.
Frequently Asked QuestionsQuestions about AI myths and facts
Does AI think like a human?
No current AI system is known to reproduce the full way humans think, experience emotions and understand the world. It can still perform some tasks that we normally associate with intelligence.
Is all AI trained on the whole internet?
No. Training datasets differ by model and may include licensed data, public data, human-created examples and synthetic data.
Can AI be completely unbiased?
No complex system can realistically be assumed free from every bias. The practical goal is to identify harmful biases, measure them and reduce their impact.
Five myths that can lead to bad decisions
Myth: “If it sounds certain, it must be correct.”
Fact: AI-generated language can be fluent and still be wrong. Consequence: verify important names, dates, calculations, quotations, and claims with independent sources.
Myth: “AI understands every question like a person.”
Fact: a system can produce a useful response without having human experience or a complete model of the situation. It may miss sarcasm, local context, or unstated assumptions. Consequence: explain the context and check whether the answer addresses the actual need.
Myth: “More data always makes AI better.”
Fact: duplicated, outdated, biased, or wrongly labelled data can make a model worse. Consequence: data quality and representativeness matter as much as volume.
Myth: “AI removes the need for expertise.”
Fact: expertise helps a person define the task, recognise implausible results, and judge trade-offs. Consequence: use AI to support a skilled process, not as a substitute for understanding the work.
Myth: “An AI result is neutral because a computer produced it.”
Fact: systems reflect choices about data, labels, objectives, thresholds, and deployment. Consequence: test how errors are distributed and provide a way to appeal important decisions.
Apply a quick evidence check
When someone makes a claim about AI, ask what system was tested, what task it performed, what the comparison was, how errors were measured, and whether the results apply to your situation. A demonstration can show that something happened once; it does not establish that it will work reliably for everyone.
Further reading: NIST AI Risk Management Framework; UNESCO's work on artificial intelligence.
One missed example does not prove an entire technology is useless
A system can fail at exact arithmetic and still help reorganise notes. It can also succeed on a demonstration and fail under different conditions. Both universal conclusions skip the question that matters: which task, input and measure of success are being tested?
A fair comparison uses the same task and relevant constraints. Record the tool version, supplied context and whether it could retrieve external information. Compare errors that affect the outcome, not just whether you liked the wording. This avoids turning a single screenshot into a claim about every model.
If two AI tools repeat the same statement, have you obtained two independent sources?
Not necessarily. They may reflect overlapping training material, copied web pages or the same flawed source. Independence concerns where the evidence came from, not the number of interfaces repeating it.
An AI says it is definitely conscious. What can you conclude from that sentence alone?
One reasoned response
You can conclude that the system produced that statement. The sentence alone does not establish subjective experience or settle the scientific and philosophical question.
Source and further reading: NIST
How to check an AI claim before sharing it
Suppose a post says, “This AI is 99% accurate.” That number is incomplete without context. Accurate on which task, using what test data, compared with what baseline, and with what kinds of mistakes? If 99% of a test set contains ordinary cases, a system can score highly while failing on the rare cases that matter most.
Use a five-question evidence check
- Who made the claim, and do they benefit if you believe it?
- Is the system and task described precisely enough to reproduce?
- Was it tested on data separate from the data used to build it?
- Are different kinds of errors reported, not just one overall score?
- Does an independent source find similar results in a real setting?
Consider a school tool that predicts which learners may need extra support. Even if the overall score looks good, teachers should ask whether errors affect some groups more than others, whether the data is current, and whether a learner can challenge an incorrect result. The number alone cannot answer those questions.
Separate evidence from possibility
A demonstration shows what happened in one setup. A benchmark measures performance under specified conditions. A field study examines use in a real environment. Each can be useful, but they answer different questions. A claim about what AI might do in the future should not be presented as proof that it already does it reliably today.
When you cannot verify a claim, say so. Sharing uncertainty is more honest than repeating a headline as fact. Start with technical documentation or an independent research summary, check its date, and read what the authors say the system cannot do.
Sources
Sources and further reading
A closer lookMany false alarms can accompany a useful detector
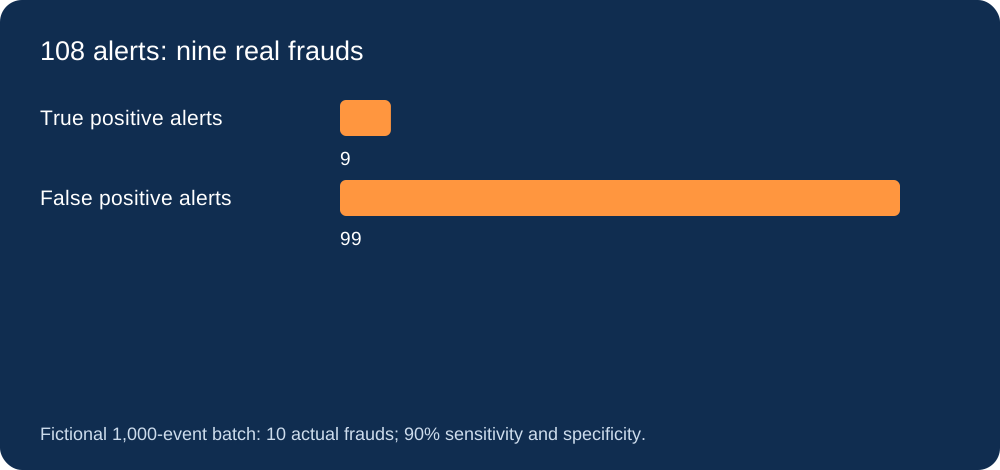
In a fictional batch of 1,000 events, ten are fraudulent. A detector flags nine of those and also flags 99 legitimate events. Only nine of its 108 alerts are actual fraud.
Work through the distinction
Sensitivity describes the nine out of ten detected frauds. It does not mean nine out of ten alerts are correct. Consider the base rate and false positives before interpreting an accuracy claim.
How many of the 108 alerts represent actual fraud?
Choose an answer to see feedback. You can try again.
Show the answer and explanation
Nine. Sensitivity describes the nine out of ten detected frauds. It does not mean nine out of ten alerts are correct. Consider the base rate and false positives before interpreting an accuracy claim.