By Ronnie Mbuqe
Training rewards patterns that help on the supplied data. Those patterns can include accidental shortcuts, such as a background associated with one class of object.
Test the same object against a different background. A sudden failure suggests the model relied on a clue that does not transfer to the intended task.
Follow the mechanism from training examples and a learning objective to a result on new input. For the wider definition and everyday uses, start with What Is AI; this guide concentrates on what changes during training and what happens during use.
Start with the core idea
New to the subject? Begin with what artificial intelligence means: then use this page to follow the journey from examples to a prediction. Continue with what AI can do today.
Where you are using it
When email moves a message to spam, a map estimates traffic or a bank flags an unusual payment, a trained model is applying patterns to new information.
What it helps with
AI can sort, rank or predict quickly. It helps people focus on likely problems, but uncertain and high-impact results still need rules or human review.
You don't need a computer science degree to understand how AI works. Let's explore the basic concepts in plain language.
Why can performance on familiar training examples exaggerate a model's usefulness?
Training adjusts a model using examples and an objective.
Trace the explanation
Evaluation needs data that was not used to teach or select the model, otherwise the test can reward memorised patterns. A useful result must transfer to the situations where the model will actually be used.
Source and further reading: Google developer documentation
Training Builds The Model; Inference Uses What Was Learned
When an AI model is trained, it sees large numbers of examples and repeatedly adjusts internal numerical parameters so its predictions become less wrong. In a language model, text is split into tokens and the model learns relationships that help it predict what token is likely to come next in context. The parameters are not a searchable library of complete sentences; they are learned numerical patterns distributed through the network.
After training, normal users usually interact with the model during inference. Your prompt is converted into tokens, processed through the network, and the model calculates probability scores for possible next tokens. One token is selected, added to the context and the process repeats very quickly until the response is complete or another stopping rule is reached.
Modern systems can add more layers around that basic model. Retrieval can search a trusted document collection and insert relevant passages into the prompt. Tool use can let the model call a calculator, database or web search. Safety systems can inspect requests and responses. The product you experience is therefore often a model plus software around it.
This explains both the strength and weakness of AI. A model can combine patterns in flexible ways and produce useful new text, but it can also generate a plausible statement that is not grounded in a verified source. When correctness matters, the system needs data, tools or human checking that connect fluent generation back to evidence.
Tokens are not exactly words
A token may be a whole short word, part of a longer word, punctuation or another text fragment depending on the tokenizer.
Parameters store learned relationships
A parameter is a numerical value adjusted during training. Large models can contain billions of them.
Context has limits
A model can only directly process a limited amount of text at one time. Long conversations or documents may need summarisation, retrieval or larger context windows.
Training changes a model; asking it a question usually uses the model
During training, an algorithm adjusts internal parameters using an objective such as predicting missing or next elements. At inference time, the trained system processes new input using those parameters. A chat interface remembering the previous sentence in its context is not automatically retraining the underlying model.
Consider a music model trained to continue note sequences. It receives a musical context, estimates possible next events and generates a continuation. Repeating that process creates a sequence. The resulting music can have familiar patterns without the model possessing a listener's memories or a performer's intentions.
Choose a learning objective to Test on separate cases
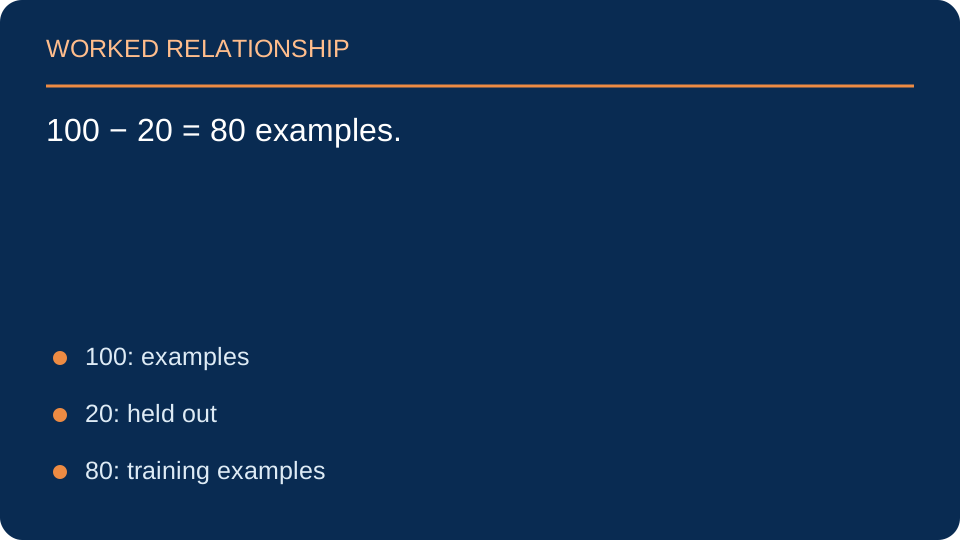
A toy dataset has 100 examples and 20 are held out before training. How many remain for training?
Trace the explanation
100 − 20 = 80 examples. This is a simple split, not a recommended universal ratio. Keep leakage out of the held-out set, including duplicate or closely related records.
Source and further reading: Google developer documentation
Why can more training make a model less useful on new examples?
A model can fit details of its training data that do not generalise. This is overfitting: improved performance on the practice material can hide poorer performance elsewhere.
Separate training and evaluation examples, and keep the final test out of tuning decisions. Otherwise the supposed exam gradually becomes part of the revision sheet.
Frequently Asked Questions
Questions about How AI Works
What makes AI work?
AI works through data, algorithms, models, training and feedback. These parts help the system learn patterns and make predictions.
What is training in AI?
Training means showing an AI system many examples so it can learn patterns from them.
Can AI be wrong?
Yes. AI can misunderstand information, repeat mistakes in data or give answers that sound confident but are not correct.
Why is data important for AI?
Data is the material AI learns from. Better data usually helps AI produce better results.
Follow one AI system from examples to a prediction
Imagine a mail service trying to identify spam. The goal is not to memorise one suspicious email. It is to learn patterns that help it judge a new message it has never seen. A responsible team first defines what counts as spam, gathers examples that are appropriate to use, removes unnecessary personal information where possible, and checks whether the examples represent the mail people actually receive.
1. Prepare examples, then train
Examples are labelled or otherwise organised so the system has a learning signal. During training, the model adjusts internal parameters to reduce the difference between its output and the training target. If the training set contains mostly obvious scam messages and very few ordinary newsletters, the model may learn a narrow idea of spam. More data does not automatically mean better data: duplicates, incorrect labels, old patterns, and unrepresentative examples can mislead the system.
2. Test on examples it has not learned from
A separate test set helps answer a more useful question: does the model generalise? If the same emails appear in both training and testing, the score can look excellent while hiding poor performance on new mail. Teams should examine different kinds of mistakes, not only one overall accuracy number. A false positive blocks a legitimate message; a false negative lets a spam message through. Which error matters more depends on the use case.
3. Predict, monitor, and improve
When a new message arrives, the trained model produces a score or category. A threshold turns that result into an action, such as placing a message in the junk folder. A borderline result might instead be shown to the user for review. After release, teams need to monitor changes: scammers adapt, language changes, and legitimate businesses send unusual messages too. Feedback should be checked for quality before it becomes new training data.
Try the decision yourself
A message says: “Your parcel is delayed. Pay a small fee using this unfamiliar link.” Do not decide from the wording alone. Check the sender address, whether you expected a parcel, the destination of the link, and whether the delivery company confirms the request through its official app or website. A model can flag the message, but it cannot guarantee that a link is safe.
Key lesson: training creates a model; testing checks whether it learned useful patterns; prediction applies those patterns; monitoring checks whether they remain useful. These are different jobs, and skipping one creates avoidable risk.
Further reading: Google's Machine Learning Crash Course explains training, evaluation, and generalisation; NIST's AI Risk Management Framework discusses risk management across an AI system's life cycle.
A model can optimise the wrong target very efficiently
A recommendation system rewarded for immediate clicks may learn to favour exciting titles. That is different from measuring whether a reader understood an explanation or returned satisfied a week later. The training objective and the human goal need not coincide.
This is why evaluation needs examples outside the training process and measures relevant to the real task. Ask which mistakes matter: missing a dangerous message, wrongly blocking a legitimate one, or generating a confident false explanation. One average score can conceal an important difference between those failures.
If a chatbot repeats your correction later in the same chat, has its underlying model necessarily changed?
No. It may simply be using the correction as part of its current context. Persistent model changes require a separate training or updating process, depending on the system.
A model succeeds on yesterday's records but fails in a new region. Which assumptions would you investigate?
One reasoned response
Compare the data distribution, labels, missing values and operating conditions. Check whether the evaluation represented the new setting rather than assuming the model understands the domain in the human sense.
Source and further reading: Google developer documentation
Walk through a real task: spotting a suspicious message
Imagine an email says that a parcel is waiting and asks you to sign in through a link. An AI-assisted spam filter may examine signals such as the sender, the domain behind the link, wording patterns, message structure, and how similar messages were treated before. It combines these signals to estimate whether the message resembles unwanted or dangerous mail. It does not prove that the message is fraudulent simply because one signal looks unusual.
From examples to a decision
- Collect examples: a training set contains messages labelled as spam or legitimate. Labels can be wrong, so the examples need checking.
- Learn patterns: training adjusts model parameters so the system can distinguish patterns in the examples.
- Test on unseen messages: evaluation checks whether the system generalises beyond the messages it learned from.
- Choose a threshold: a stricter threshold may block more spam but can also hide legitimate mail; a looser one may let more spam through.
- Monitor new cases: scammers change wording and domains, so performance can drift and needs review.
Two different mistakes
A false positive is a legitimate message sent to spam. A false negative is a harmful message that reaches the inbox. These errors have different costs: missing a bank phishing attempt may be serious, while misclassifying a harmless newsletter is usually less serious. Good systems consider the task's risks and provide a way to report mistakes.
Try it yourself: inspect a suspicious message without clicking its links. Check the sender address, visit the organisation's website by typing its known address, and contact it through a separate trusted channel. AI can flag risk, but it should not be the only basis for deciding whether to trust a message.
Sources
Sources and further reading
A closer lookTraining examples are not the final exam
A classifier learns from labelled examples and achieves excellent results on those same records. That result alone does not show how it handles new messages.
Work through the distinction
Keep evaluation data separate and representative of the intended use. Prevent related copies from leaking across the split. When deployment conditions change, old evaluation results may no longer describe current performance.
Where should generalisation be tested?
Choose an answer to see feedback. You can try again.
Show the answer and explanation
On appropriate held-out examples. Keep evaluation data separate and representative of the intended use. Prevent related copies from leaking across the split. When deployment conditions change, old evaluation results may no longer describe current performance.