By Ronnie Mbuqe
An algorithm describes the steps used to reach a result. The number of steps can grow very differently depending on the method.
Checking every name in a list is different from repeatedly halving an already sorted search range. The second method needs the sorting condition to be valid.
A fast search can discard the answer if its list is not sorted
Binary search saves work by ruling out half the remaining candidates. That shortcut depends on order. If the values are shuffled, the same instruction can eliminate the place where the answer actually sits.
We will walk a small sorted list before comparing step counts. By the end, you should be able to state the method's assumption and explain when a simple scan may still be the sensible choice.
Practical examples: What Is an Algorithm
Google
A search engine does not simply find pages containing a word. Ranking methods consider relevance, authority, freshness, language and location, then order enormous numbers of candidates. The exact formula changes because low-quality publishers also try to manipulate it.
Google
Map software compares possible routes using distance, road speed, traffic, closures and allowed turns. “Shortest” and “fastest” are different goals, so changing the priority can produce a different but still correct route.
Netflix
A streaming recommendation method compares viewing history, similar audiences and information about each programme. It predicts what may hold attention; it does not understand personal taste perfectly, which is why feedback and diversity controls matter.
Bank
A bank may score a payment using amount, location, device, merchant and recent activity. A high score can trigger verification instead of automatic rejection. The institution must balance fraud prevention against blocking legitimate customers.
Can two correct search methods require very different amounts of work?
An algorithm is a method for reaching a result.
Trace the explanation
On sorted data, repeatedly eliminating half the remaining range can avoid checking every item. That advantage depends on the ordering assumption being valid.
Source and further reading: NIST
A faster search can be wrong if the list is not in order
Binary search repeatedly discards half a sorted range. Its speed comes from using order: if the middle value is smaller than the target, values before it can be excluded. On an unsorted list that inference fails, even if the code runs perfectly.
Try the sorted list 2, 4, 7, 9, 13, 18, 21. Searching for 18 checks the middle region and narrows the candidates. Shuffle the list and the same elimination rule can discard the answer. An algorithm's preconditions are part of its correctness.
Search for 18 in seven ordered values
Start with 2, 4, 7, 9, 13, 18, 21. The middle value is 9. Since 18 is greater and the list is sorted, all values at or before 9 can be excluded.
The remaining range is 13, 18, 21; its middle is 18, so the search succeeds on the second comparison in this chosen example. Searching for a value that is not present eventually leaves an empty range rather than a guessed match.
Sorting has a cost. For one lookup in a tiny unsorted list, scanning may be simpler. For repeated lookups in suitably organised data, a preparation cost can pay off. The comparison-count calculator below excludes that setup and is not a measurement of actual processor time.
How many comparisons did this particular seven-value example use to find 18?
This checks a prediction about the worked example. It does not run server code, contact an API or change a booking.
Two in this example: compare with 9, then with 18. This is not a promise that every seven-item search needs exactly two checks.Read the explanation without the checker
Two in this example: compare with 9, then with 18. This is not a promise that every seven-item search needs exactly two checks.
Shuffle the list and explain which elimination step is no longer justified. The code's speed cannot repair a false precondition.
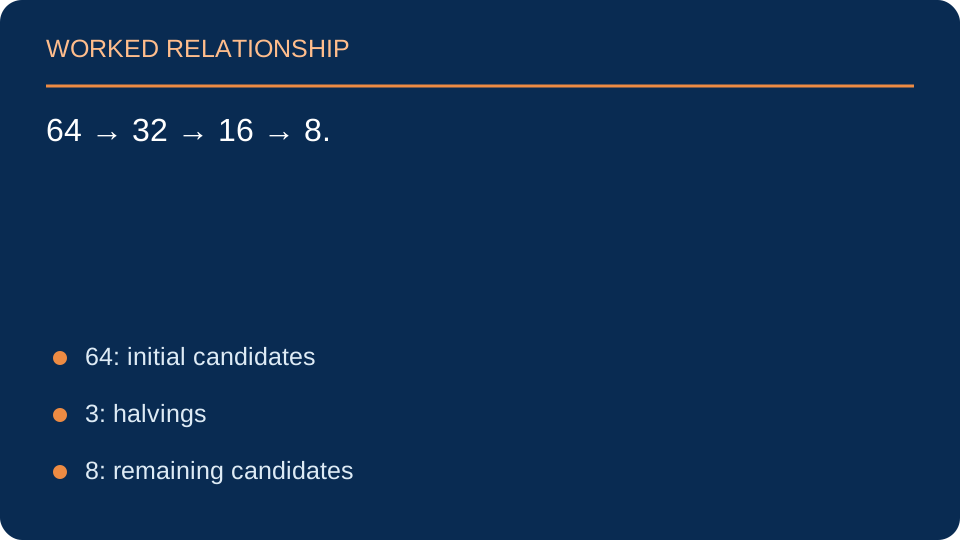
A search halves a set of 64 possibilities three times. How many possibilities remain?
Trace the explanation
64 → 32 → 16 → 8. Each step removes half the remaining candidates, not half the original total. If the data is not sorted appropriately, the elimination rule may discard the right answer.
Source and further reading: NIST
Why is the fastest method sometimes the wrong choice?
Speed is only one requirement. Memory use, correctness, setup cost and maintainability can matter more for a particular task.
A tiny list may not justify a complicated structure. Choose a method for the actual scale and constraints, then measure where the time goes.
Move from ordered steps to the data and code that execute them
Programming expresses an algorithm in a form a computer can run, while SQL supplies and reshapes the structured data many algorithms need. For systems that rank or generate instead of follow one fixed answer, read how developers use and verify AI-assisted output.
The cheapest method depends on what work happens before the search
If you only need one lookup in a small unsorted list, scanning it may be simpler than sorting it first. If you need many lookups, paying the sorting or indexing cost can be worthwhile. Comparing only the final search step hides that preparation.
This is a practical way to evaluate an algorithm: define the result, check the assumptions, count the important work and include setup costs. The comparison calculator shows growth in step counts, not a promise about wall-clock speed on every computer.
Count comparisons before timing the code
Linear search can inspect the whole list. Binary search repeatedly halves a sorted range; preparation costs are excluded.
Can two different algorithms produce the same correct answer?
Yes. They may differ in time, memory use, setup requirements and how easily their behaviour can be explained. Correctness does not select one universally best implementation.
Questions about What Is an Algorithm?
Is an algorithm always complicated?
No. Some algorithms are very simple, like checking if a number is bigger than another.
Do AI systems use algorithms?
Yes. AI uses many algorithms to learn patterns, make predictions and generate responses.
Is an algorithm the same as code?
No. An algorithm is the method or logical procedure. Code is one way of implementing that method in a programming language.
What makes an algorithm efficient?
Efficiency considers how time and memory grow as the input becomes larger. A method that is fine for ten records may be unsuitable for millions.
Can two algorithms give the same answer?
Yes. Many problems have several correct approaches. Developers choose between them based on simplicity, performance, memory, reliability and constraints.
Do algorithms make decisions by themselves?
They follow the rules and data they are given. Human choices determine the objective, available inputs and what counts as an acceptable result.
A real decision processAn algorithm is useful because the steps remove guessing
Say a website needs to show the cheapest available room. “Find a cheap room” is too vague for a computer. The instruction has to become a repeatable process: load rooms for the selected dates, remove rooms that are unavailable, compare the remaining prices, sort from lowest to highest, and return the first result. That sequence is an algorithm.
Two algorithms can produce the same answer but take very different amounts of work. If a system has ten records, almost any sensible approach feels fast. If it has ten million records, the way the search or sort is designed becomes important. Computer science studies this efficiency so developers can predict how an approach behaves as the amount of data grows.
Algorithms are not the same as AI
An ordinary algorithm follows rules chosen by people. A tax calculation, password-length check or alphabetical sort can be completely deterministic: give it the same input and it follows the same steps to the same result. Machine-learning systems are different because part of their behaviour comes from patterns learned from training data. They still use algorithms, but “algorithm” does not automatically mean “artificial intelligence.”
Good algorithms also account for awkward inputs. What happens if there are no available rooms? What if two prices are equal? What if the date is invalid? Handling those cases is part of designing the process, not an afterthought.
Would you choose a complicated search structure for a list of three fixed options?
One reasoned response
Probably not without another reason. Consider list size, update frequency and implementation cost. The fastest asymptotic method is not automatically the clearest or most useful choice for every tiny problem.
Source and further reading: NIST
Example: an algorithm to find the largest number
An algorithm is a finite set of steps for solving a problem. It can be described in plain language before it is written in a programming language.
numbers = [8, 3, 14, 6]
largest = numbers[0]

for number in numbers:
    if number > largest:
        largest = number

print(largest)  # 14
The algorithm begins by treating the first value as the largest seen so far. It then checks every value and replaces that candidate when it finds a bigger one. For an empty list, this version would fail because there is no first value; a complete design must define how that case should be handled. This is a key lesson: an algorithm needs both a clear procedure and clear assumptions about its input.
Sources
Sources and further reading
A closer lookBinary search needs an ordering rule
Finding a surname by repeatedly halving a list works only when the list is sorted consistently. On an unsorted list, discarding half can discard the answer.
Work through the distinction
State the precondition before comparing speed. For a list with 1,024 ordered entries, halving reduces the candidate interval about ten times to one entry; exact comparison counts depend on the implementation and whether the match exists.
What must be established before binary search?
Choose an answer to see feedback. You can try again.
Show the answer and explanation
A compatible sorted order. State the precondition before comparing speed. For a list with 1,024 ordered entries, halving reduces the candidate interval about ten times to one entry; exact comparison counts depend on the implementation and whether the match exists.